

Introduction
In order to adapt to their role as predator or prey, animals have developed various strategies. The ability to produce venom in specialized glands or cells and inject it into the target animal through a wound is one of these adaptations. In the animal kingdom, venom and toxic secretions are both complex combinations used for de-fense, predation, communication, and competition [1, 2]. Bioactive substances such as proteins, peptides, salts, and metabolites such as amines, amino acids, and alkaloids are the various types of molecules that make up venoms. The venom of a single animal can contain hundreds of different components, each serving various biological purposes [3]. Studies of animal venoms have continued to evolve with technological advances, creating oppor-tunities for the discovery of new bioactive molecules. With the introduction of “omics” technologies for venom research, such as proteomics, transcriptomics, genomics, and metabolomics, it has become possible to collect and analyze data on a large scale. One of the recently developed techniques for molecular phylogenetic analysis, biology, medicine, and especially for the identification of novel genes in non-model organisms is transcriptome sequencing [4]. Metabolomics, the most recent development in the field of ‘omics’ technologies, aims to identify and quantify the entire set of metabolites present in cells, biological fluids, and tissues (the so-called metabolome). The endogenous metabolites are at the end of a series of processes that begin with the genome and continue with the transcriptome and proteome. The metabolome thus closes the gap between a particular genotype and pheno-type. The components of the metabolome include classes of compounds such as amines, amino acids, organic acids, steroids, alkaloids, and sugars. The term “metabolomics” was introduced in 1999 by Nicholson, Lindon, and Holmes [5]. Metabolomic and proteomic studies and the identification of new biochemical markers by LC-MS/MS, which are frequently used in diseases, can contribute to the development of preventive and therapeutic strategies [6].
Scorpions belong to the order Arachnid (Arachnida) and have attracted the attention of researchers due to their venomous components and the fact that they are ancient terrestrial animals that are also considered living fossils [7, 8]. The species A. crassicauda and L. abdullahbayrami are responsible for the majority of scorpion stings in our country, which is one of the endemic regions. In addition, the two most important species responsible for severe clinical findings and mortality are A. crassicauda and L. abdullahbayrami [9]. The toxicity of the venom of H. saulcyi is slightly lower than that of A. crassicauda. However, it is important for human health as it causes severe pain and sweating in scorpion stings [10]. A. crassicauda is a common scorpion species in Turkey and can cause serious poisoning in humans. A. crassicauda is reported to occur mainly in Eastern and Southeastern Anatolia, in the provinces of Elazığ (Palu), Diyarbakır, Şanlıurfa (Harran – Akçakale), Mardin, Adana, Hatay, Malatya and Mersin in Turkey [10, 11]. The venom of A. crassicauda contains toxins that are especially effective on sodium channels [12]. The venom of H. saulcyi is slightly less toxic than that of A.crassicauda. Nevertheless, it is important for human health as it causes severe pain and sweating in scorpion stings. H. saulcyi is generally distributed in the provinces of Mardin, Batman, Şırnak and Hakkari in the Southeast Anatolia region of Turkey [13]. L. abdullahbayrami is endemic to Turkey and occurs in and around the provinces of Gaziantep, Adıyaman, Kilis, Şanlıurfa, and Mardin provinces in southeastern Anatolia [14]. Scorpion venom consists of a combination of many biologically active substances, including enzymes (such as hyaluronidase, phospholipase, and protease), carbohydrates, free amino acids, lipids, toxic peptides, and other metabolites [15, 16]. Since scorpions use their venom to capture prey, protect themselves from predators, and reproduce, some venom components are essential for the scorpion’s survival [15]. Scorpion venom is a complex mixture of biogenic amines, small peptides and large proteins, mucoproteins, and other components produced by the columnar epithelial cells of the venom gland [17].
Mainly due to the heterogeneity, complexity, and high variability of the venom composition and the low solubility of existing methods to separate the venom proteins separa-tion methods, the amount of venom peptides discovered is much lower than expected [18–20]. The first cDNA library for scorpion venom glands was created in 1989 for the scorpion Androctonus australis. This library contains collections of cDNA sequences cloned into vectors [21]. Subsequently, transcriptomic analyses of the scorpion venom gland have been greatly improved by the introduction of high-throughput sequencing.
The aim of this study was to perform transcriptomic analysis of mRNA transcripts in tissues collected from venom glands of the scorpion species A. crassicauda, H. saulcyi, and L. abdullahbayrami and to analyze the metabolic venom. As a result of the transcriptome study of these scorpion species, the amino acid sequences in the possible proteins in the venom glands are determined and the venom contents and the amino acids in the venom are compared by analyzing the profile of free amino acids profile analysis. The peptide maps and metabolic analyses of the venoms will be elucidated by transcriptomic analysis of the mRNA profiles of tissues from the venom glands of the scorpions A. crassicauda, H. saulcyi, and L. abdullahbayrami.
Material and Method
Sample Collection and Venom Milking
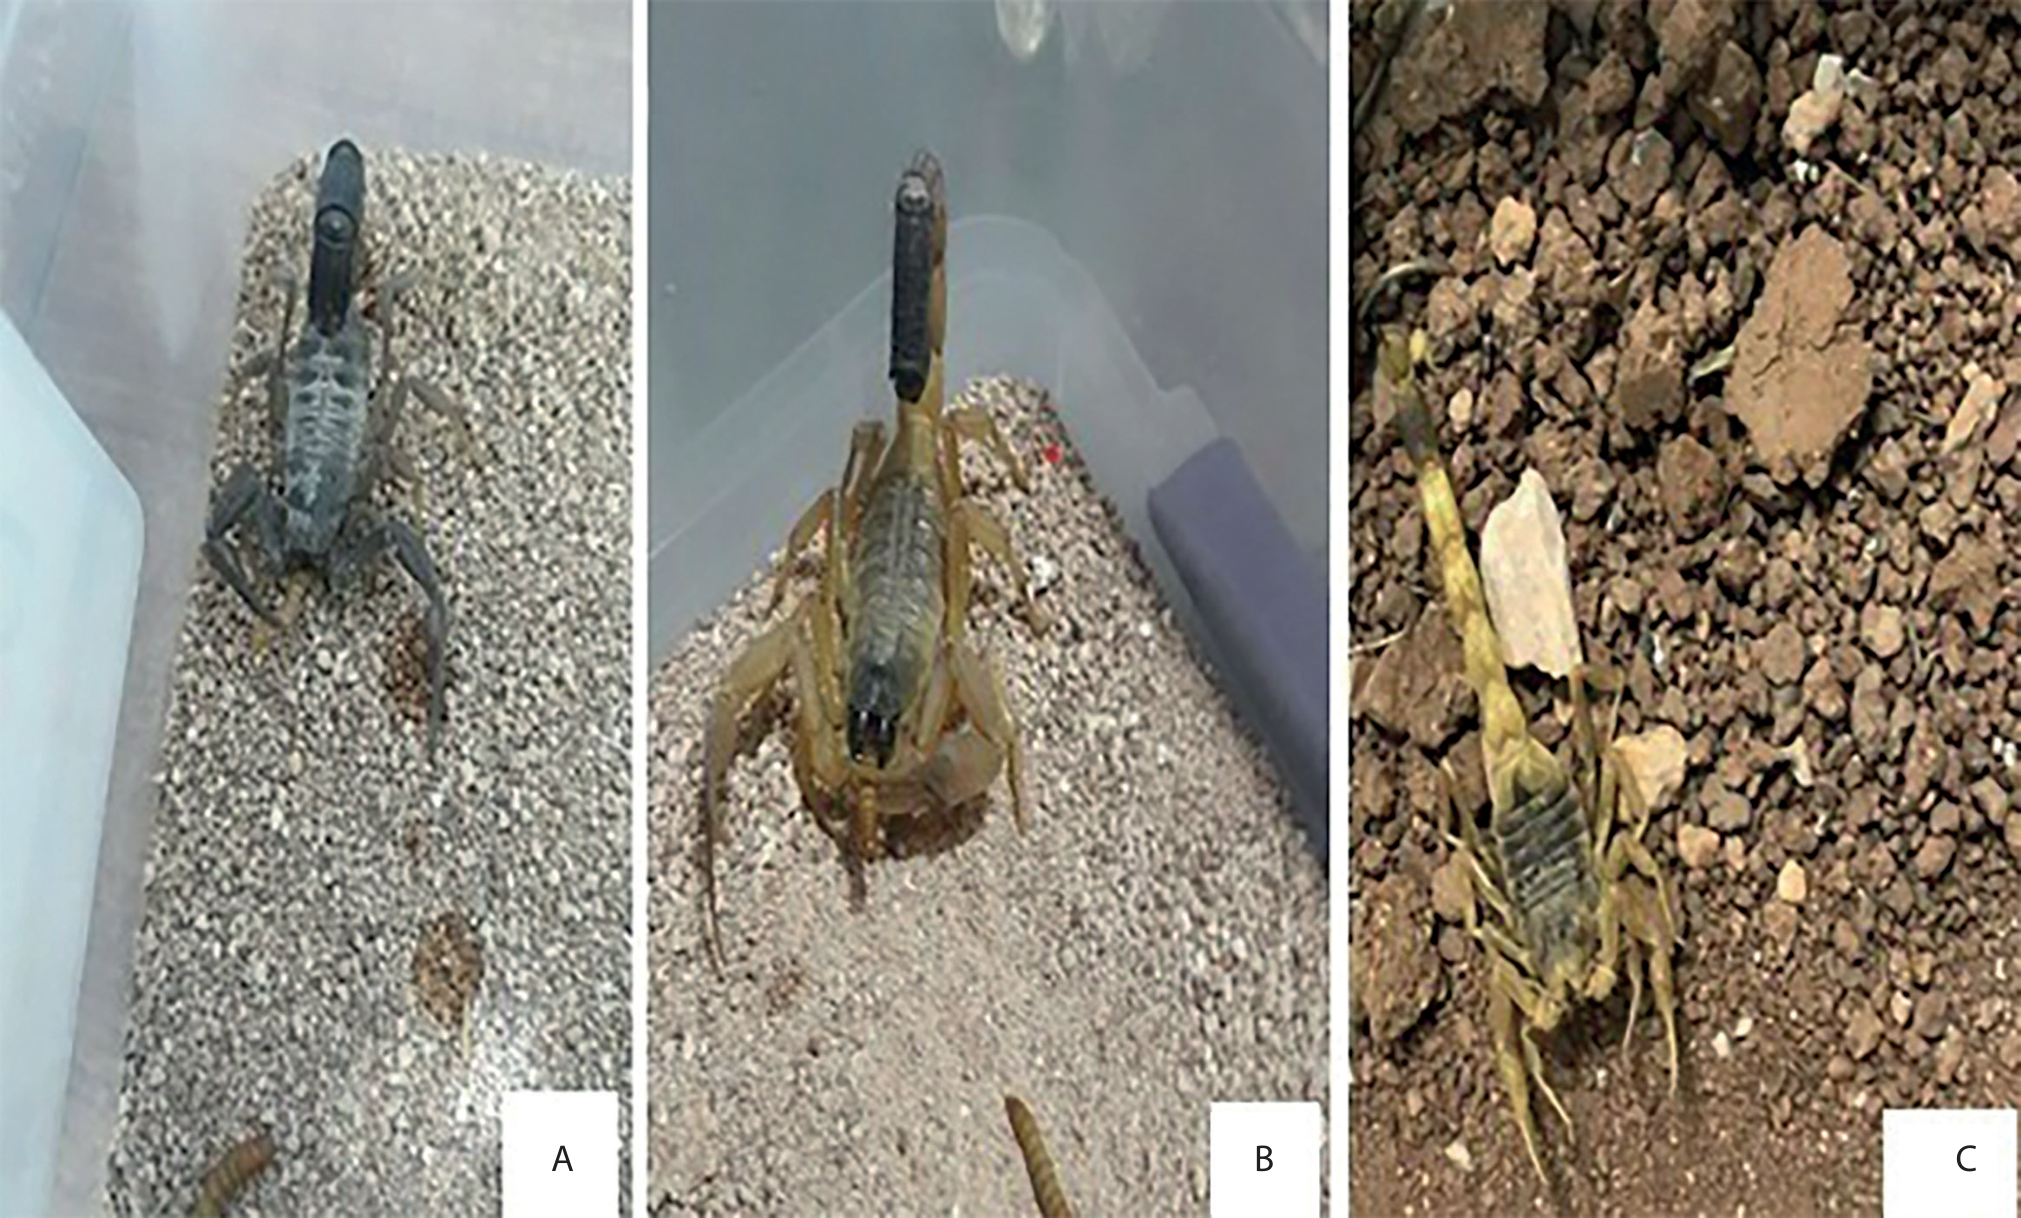
The species A. crassicauda and L. abdullahbayrami were collected in the province of Şanlıurfa and the species H. saulcyi species were collected in the province of Şırnak. During the field studies, a total of 30 scorpions, 10 of each scorpion species, were collected. The scorpions were captured during the day and at night during field surveys. The captured specimens were placed in plastic containers with lids and brought to the laboratory. The scorpions brought to the laboratory were fed with mealworms once a week to adapt to the environment (Fig. 1). The specimens collected in the field were injected with venom. The venom was milked using the electrical stimulation method by applying current in the range of 12–16 volts. The telson of the scorpions was cut off 3 days after milking. The venom and the telson of the milked scorpions were stored in a freezer at -80°C until the required analyses were performed.
mRNA Isolation and cDNA Library Preparation
Commercial miRNeasy kits (QIAGEN:217004) and a total RNA isolation kit were used for transcriptome analysis of the venom tissues obtained. At the beginning of the isolation, the venom glands of each scorpion species were cut open and placed in separate microcentrifuge tubes. The isolation steps were performed according to the protocol of the kit. RNA concentration and quality control were performed using the RNA 6000 Pico Kit (Agilent Technologies, USA) on an Agilent Bioanalyzer 2100.
RNA Quality Control
For quality control of the isolated total RNA material, measurements were performed with a 4200 TapeStation system (Agilent, USA, #G2991BA).
Library Preparation (mRNA Preparation)
The Illumina Stranded mRNA Preparation Kit (Illumina, USA, 20040534) was used for library preparation of the isolated RNA material. The kit is based on the separa-tion of targeted mRNAs in the whole RNA from the poly-A tails, random fragmentation, and subsequent generation of primary and secondary cDNA chains. In library preparation, capture, fragmentation, mRNA purification, cDNA synthesis, addition of index barcode sequences, and purification were performed according to the manufacturer’s instructions.
Sequencing (Illumina NovaSeq 6000)
The NovaSeq 6000 Next Generation Sequencing platform from Illumina was used for sequencing. 150 bp paired-end reads were obtained. Quantification, dilution, and loading of the library was performed according to the manufacturer’s instructions.
Examination of the Metabolite Profile of the Venom
The venoms of the species A. crassicauda, H. saulcyi, and L. abdullahbayrami were removed from the -80°C freezer, diluted 1:1 with ultrapure water, and vortexed for 5 minutes. The JASEM amino acid kit was used to analyze the amino acids. For the analysis, it was placed in the tray compartment in the HPLC section of the LC-MS/MS (Shi-madzu 8045, Japan) and read. Mobile phase-A and mobile phase-B from the amino acid kit were used as the mobile phase. Restek LC columns were used as columns.
Bioinformatics Analyses
Adapter trimming was necessary because we found nextera transposase sequences above the threshold (>1%) in the read2 fastq files. We performed the trimming using the fastp v0.23.4 tool [22], using the adapter sequences listed in the adapter.fa file in QC_reports and also trimming for quality (min Q30 at 5’ and 3’ ends), minimum length (100 bp), and ambiguous base concentration. The adaptor sequences used for trimming were the transposase sequence of nextera (R1 TCGTCGGCAG CGTCAGATGTGTATA AGAGACAG,R2GTCTCGTGGGCTCG-GAGATGTG-TA TAAGAGACAG). The trimmed, filtered reads were mapped to the coding reference sequence of C. sculp-turatus (https://www.ncbi.nlm.nih.gov/datasets/genome / GCF_000671375.1), the sequenced scorpion species that has gene information. The mapping tool used was BWA (v. 0.7.17-r1188) [23]. We counted the reads mapped to each cds using samtools (v1.15.1) [24] idxstats and calculated the TPM value using the formula with R [25] (version 4.2.1) base functions: TPM = 106 × read count mapped on transcript/transcript length [kb]Â (read count mapped on transcript/transcript length [kb])
Results
Investigation of Metabolite Profile of Venoms
Scorpion venom contains macromolecules with a molecular weight of over 5000 Daltons and small micro-molecules such as various peptides and enzymes. In this study, the amounts of free amino acids in the venoms of A.crassicauda, H. saulcyi, and L. abdullahbayrami were determined by LC-MS/MS method. The free amino acid profile of the venom was analyzed by LC-MS and the results are presented in Table 1. The presence of the amino acids taurine, alpha-amobutyric acid, phosphoethanolamine, lysine, leucine, and arginine was detected in the scorpion venom of A. crassicauda. The presence of the amino acids taurine, lysine, phosphoethanolamine, arginine, alphaaminopimelic acid, and leucine was detected in the scorpion venom of H. saulcyi. LC-MS/MS results: The presence of alpha-aminobutyric acid, taurine, lysine, phenylalanine, arginosuccinic acid, arginosuccinic acid, leucine, histidine, arginine, pro-line amino acids were determined in L. abdullahbayrami scorpion venom.
Table 1.
Results of LC-MS/MS analysis of the free amino acid profile of the venoms of H. saulcyi, A. crassicauda, and L. abdullahbayrami venoms. (Amount detected in the venoms (nmol/L).
The amino acid distribution profiles of the metabolite analyses of the venoms of H. saulcyi, A. crassicauda, and L. abdullahbayrami species are shown in Fig. 2.
Transcriptome Analyses of the Venom Gland
The general statistics of the venom gland transcriptome analyses are given in Table 2. Repeat reads were 81.2% for A. crassicauda, 82.5% for H. saulcyi, and 75.9% for L. abdullahbayrami. GC rates were 37% for A. crassicauda, 36% for H. saulcyi, and 37% for L. abdullahbayrami. Read lengths were 134 bp for A. crassicauda, 133 bp for H. saulcyi, and 134 bp for L. abdullahbayrami, respectively. The total number of sequences was 41.6, 27.0, and 20.7 million for A. crassicauda, H. saulcyi, and L. abdullahbayrami, respectively.
The 8 different protein names, ID codes, similarity ratios, and amino acid sequences obtained as a result of transcriptome analysis in A. crassicauda species are given in Table 3. The longest amino acid sequence contains 974 amino acid sequences in colorectal mutant cancer protein-like isoform X1 protein and the shortest amino acid sequence contains 189 amino acid sequences in apoptosis regulator R1-like protein.
The 8 different protein names, ID codes, similarity ratios, and amino acid sequences obtained from the transcriptome analysis of the species H. saulcyi are listed in Table 4. The longest amino acid sequence contains 910 amino acid sequences in breast cancer anti-oestrogen resistance protein 3-like protein and the shortest sequence contains 189 amino acid sequences in the apoptosis regulator R1-like protein.
The names, ID codes, similarity ratios, and amino acid sequences of 7 different proteins obtained as a result of transcriptome analysis L. abdullahbayrami species are listed in Table 5. The longest sequence contains 970 amino acid sequences in colorectal mutant cancer protein-like protein isoform X2 protein and the shortest sequence contains 189 amino acid sequences in apoptosis regulator R1-like protein.
Fig. 2.
Distribution of A.A. profiles in metabolite analyses of venoms from the species H. saulcyi, A. crassicauda, and L. abdullahbayrami.
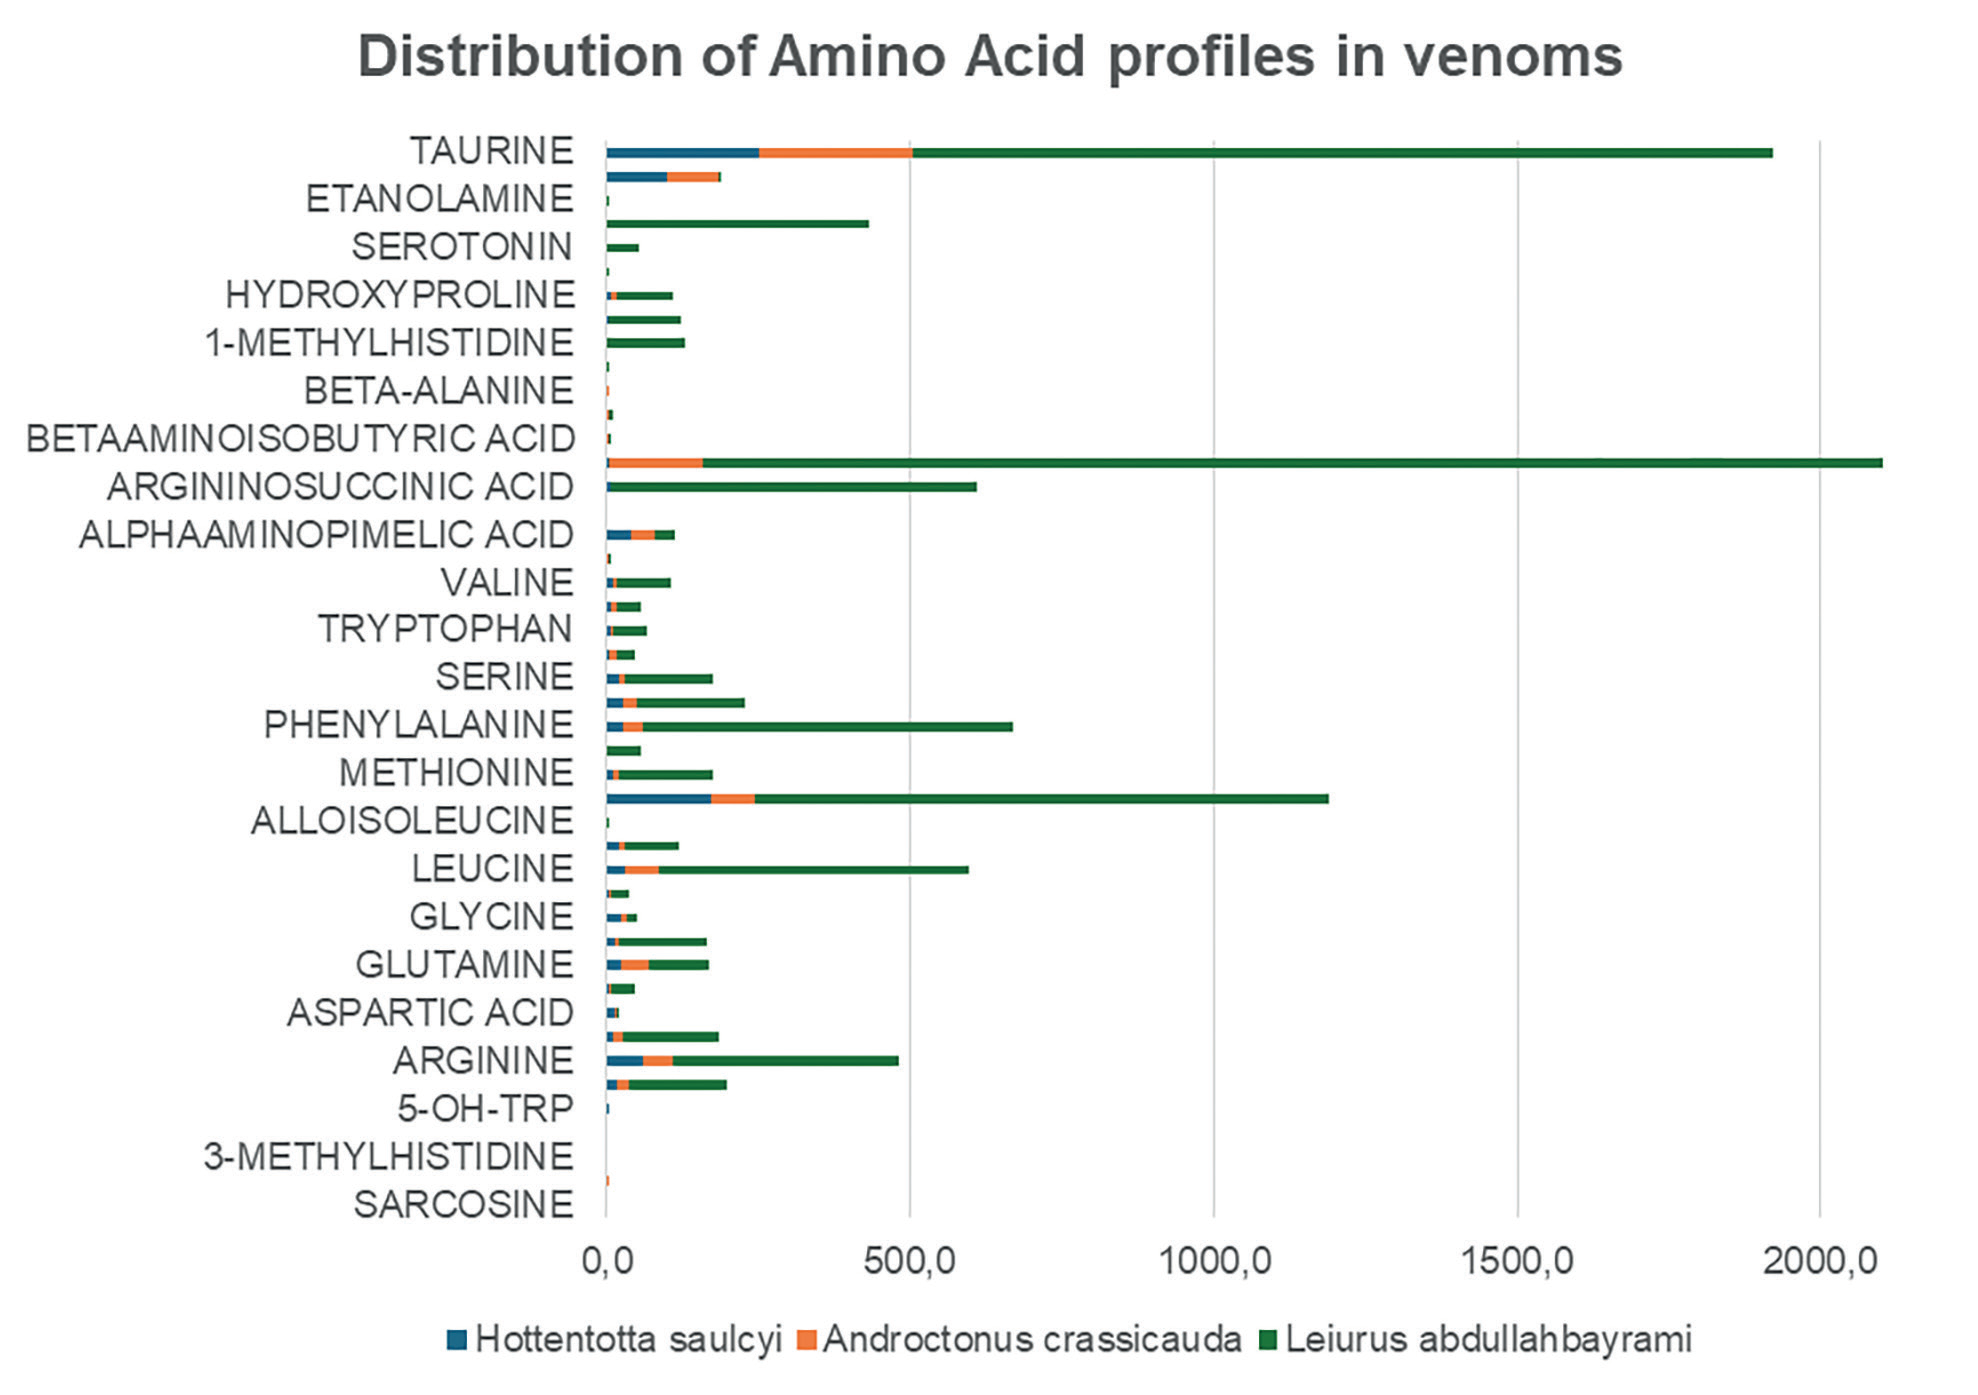
Table 2.
General statistics of venom gland transcriptome analyses in different scorpion species (AC: A.crassicauda, HS: H. saulcyi, LA: L. abdullahbayrami).
| Sample Name | % Dups | % GC | Read Length | M Seqs |
|---|---|---|---|---|
| RP23-025-AC | 81.2% | 37% | 134 bp | 41,600,000 |
| RP23-025-HS | 82.5% | 36% | 133 bp | 27,000,000 |
| RP23-025-LA | 75.9% | 37% | 134 bp | 20,700,000 |
Table 3.
8 different protein names, ID codes, similarity ratios and amino acid sequences obtained as a result of transcriptome analysis in A. crassicauda.
Table 4.
8 different protein names, ID codes, similarity ratios and amino acid sequences obtained from the transcriptome analysis of H. saulcyi.
Table 5.
Names, ID codes, similarity ratios and amino acid sequences of 7 different proteins obtained as a result of transcriptome analysis in L. abdullahbayrami.
Discussion
Transcriptomic analyses are among the most important molecular studies of recent years. In particular, the sequencing of transcripts encoding venom components from venom glands has made it possible to identify structures with low density or low ionizable potential in proteomic analyses. In this way, it will be possible to understand these small potential new structures and their functions that cannot be detected due to the physicochemical properties of venom components. Sanger sequencing of expressed sequence tags (ESTs) was used to perform the first transcriptome analysis of scorpion venom glands [26].
Currently, NGS technologies, including pyrosequenc-ing, form the basis for transcriptome analysis and expression-based sequencing (Illumi-na) [26]. Previous studies reported 37 transcriptomes of scorpion venom glands belonging to 7 of the 20 existing scorpion families.
Our transcriptome analyses of the venom glands of various scorpion species led to the identification of 35,540 peptides. Of these, 9,254 were unidentified proteins, 124 were venom proteins (venom allergens, venom factor-like proteins, venom metallo-proteinases) and the rest were enzymes, AMPs, and cancer-related proteins. The overall statistics of our venom gland transcriptome analyses are as follows: 81.2% for A. crassicauda, 82.5% for H. saulcyi, and 75.9% for L. abdullahbayrami. GC rates were 37% for A. crassicauda, 36% for H. saulcyi, and 37% for L. abdullahbayrami, respectively. The read lengths were 134 bp in A. crassicauda, 133 bp in H. saulcyi, and 134 bp in L. abdullahbayrami, respectively. Finally, the total number of sequences amounted to 41.6 million in A. crassicauda, 27.0 in H. saulcyi, and 20.7 million in L. abdullahbayrami. Quintero-Hernández et al.[8] 83,812,864 raw reads were obtained from the transcriptome of the venom gland of the scorpion species U. yaschenkoi. After re-moving concordances, ambiguous reads, and low-quality reads, the sequence data yielded 83,808,178 assignable reads. The average read length was 101 nt and the transcriptome size corresponded to 8,464,625,978 nucleotides (8.4 Gb) [8]. U. yaschenkoi in the scorpion species, only 51% of 62,505 individual genes in the databases searched were found to be significant in the databases searched. Only 3,900 of these sequences had similar sequences to toxins, venom-related components (such as hyaluronidase, phospholipase, and other enzymes), and housekeeping genes (e.g. heat shock protein, β-actin, RNA-binding protein). For the toxin genes, they obtained a total of 3900 sequences (unigenes) that were compatible with the sequences pub-lished in GenBank. These sequences were then manually analyzed to select only those coding for toxins, antimicrobial peptides, and venom-specific components. They identified 210 sequences encoding 111 unique amino acid sequences, including venom toxins and proteins involved in venom production [26].
SO et al. [27] using a combination of transcriptomic and proteomic approaches, putative conserved toxins from the venom glands of the scorpions Liocheles australasiae, Mesobuthus martensii, and Scorpio maurus palmatus were identified and compared. The transcriptome sequencing on the three scorpion venom glands produced 40,644,404−45,175,588 clean reads. Subsequent assembly processes produced 43,481, 24,054, and 40,432 transcript sequences for M. martensii, S. maurus palmatus, and L. australasiae, respectively. Among these assembled transcripts, 22,215, 10,045 and 14,145 sequences could be functionally annotated. For the venom gland proteomes, a total number of 1,644 (M. martensii), 830 (S. maurus palmatus), and 1,269 (L. australasiae) [27].
Zhong et al. [28] fully investigated the composition of venom gland peptides in Hadogenes troglodytes using a transcriptomic approach. They discovered 121 new peptides from scorpions, including 20 new types of peptides cross-linked with one, two, three, four, or seven disulfide bridges, 11 new K+ channel toxin-like peptides, and 2 new ryanodine receptor-specific toxins, respectively [28]. In the species H. saulcyi studied by us, 8 different proteins were obtained as a result of the transcriptome analysis; Venom protease-like (amino acid sequence length 390), venom metalloproteinase antarease-like TtrivMP_A (amino acid sequence length 739), breast cancer antiestrogen resistance protein 3-like (amino acid sequence length 910), BRCA2 interacting transcriptional repressor EMSY-like isoform X2 (amino acid sequence length 888), Apoptosis regulator R1-like (amino acid sequence length 189), venom phosphodiesterase 2-like (amino acid sequence length 770), serologically defined colorectal cancer antigen 3 homolog (amino acid sequence length 377) and colorectal cancer mutant cancer protein-like isoform X3 (amino acid sequence length 812). In the scorpion species U. yaschenkoi, [8] the venom protein f-spondin-1-like, the venom protein (spondin-like) venom protein-9, the venom insulin-like venom protein 302-like and the toxin-like venom protein-7 were detected. The proteins detected in our study in the scorpion species H. saulcyi were venom metalloproteinase antarease-like TtrivMP_A, venom protease-like, and venom phosphodiesterase-2-like. In this study, 8 different proteins were identified and selected in the species A. crassicauda and H. saulcyi, and 7 different proteins in the species L. abdullahbayrami. The selection was based on the fact that the selected proteins are venom- and cancer-relevant proteins. Based on the data obtained in this study, proteins were identified that could have a potential for cancer treatment. Kayhan et al. [29] statistically analyzed the results of the cytotoxic effects of raw scorpion venom on MCF-7 and A549 cancer cells and L929 fibroblast cells separately using the Mann-Whitely U test. It was found that while the percentage viability value of L929 cells was very close to the A-549 value, the percentage viability value of MCF-7 cells was higher than the L929 value, but the difference in the study was not statistically significant. When the proliferation curves of these cells were examined, it was found that the highest dose of venom slightly decreased the proliferation of MCF-7 and L929 cells, but did not affect the proliferation of A549 cells. They observed the apoptotic and antiproliferative effects of the crude scorpion venom of M. gibbosus on MCF-7 and A549 cancer cells to some extent [29]. Valdez-Velázquez et al. [30] reported comprehensive venom characterization using high-throughput proteomic and Illumina transcriptomic sequencing performed with purified RNA from Centruroides hirsutipalpus scorpion venom glands. 2,553,529 reads were assembled into 44,579 transcripts. From these transcripts, 23,880 were successfully annotated using Trinotate. Using specialized databases and by performing bioinformatic searches, it was possible to identify 147 putative venom protein transcripts. The venom of C. hirsutipalpus contains the highest reported number (77) of transcripts encoding NaScTxs, which are the components responsible for human fatalities [30].
Setayesh-Mehr et al. [31] focused on the fraction of Hemiscorpius lepturus scorpion venom. Two bioactive fractions (F2 and F4) were separated and collected by RP-HPLC. The cytotoxicity of F2 and F4 against human red blood cells and the MCF-7 cell line was then investigated. In the analyses, they determined that Bax and p53 expression increased in MCF-7 cells treated with fractions compared to untreated control cells, while Bcl-2 expression decreased. In vivo analysis results determined that the level of IFN-γ increased in mice treated with F2 and F4 at concentrations of 5 and 10 mg/kg compared to control animals, whereas the level of IL-4 decreased significantly (10). p < 0.0001). In conclusion, two extract fractions of H. lepturus scorpion venom may exhibit anti-cancer properties and can modulate the immune system and induce apoptosis in cancer cells [31].
In the A. crassicauda species examined by us, 8 different proteins were identified as a result of the transcriptome analysis. These proteins are Breast Cancer Anti- Oestrogen Resistance Protein 3-like (amino acid sequence length 910), BRCA2 interacting transcriptional repressor EMSY-like isoform X1 (amino acid sequence length 889), apoptosis regulator R1-like (amino acid sequence length 189), venom phosphodiesterase 2-like (amino acid sequence length 770), serologically defined colorectal cancer antigen 3 homolog (amino acid sequence length 377), C3 and PZP-like alpha- 2-macroglobulin domain containing protein8 (amino acid sequence length 367), colorectal mutant cancer protein-like isoform X1 (amino acid sequence length 974) and venom metalloproteinase 3-like isoform X1 (amino acid sequence length 658). The venom neuropeptide was identified as a venom protein in the scorpion species Parabuthus stridu-lus. In our study, we identified a venom protein similar to phosphodiesterase-2 in A. crassicauda. Naderisoorki et al. [32] 11 isolated ESTs associated with the sodium channel in the scorpion species Odonthubuthus doriae sodium channel. The coding sequences and peptide sequences of these 11 isolated ESTs were determined and then the signal peptides of each EST were predicted using signal peptide prediction tools. Finally, the mature peptides were predicted by deleting the signal peptides. Analysis of these mature ODNaTx peptides showed that the total number of amino acids in 8 of these peptides was similar to the ODNaTx peptides in the Buthidae family [32].
Romero-Gutierrez et al. [33] reported a detailed examination of venom gland transcripts and venom composition of the Mexican scorpion Thorellius atrox. By RNA-seq performed with the Illumina protocol, more than 20,000 assembled transcripts were obtained. Following a database search and annotation strategy, 160 transcripts were identified that potentially encode venom components. Mass fingerprinting by LC-MS identified 135 individual venom components; five of these matched the theoretical masses of putative peptides translated from the transcriptome. LC-MS/MS de novo sequencing allowed the reconstruc-tion and identification of 42 proteins encoded by the assembled transcripts [33]. In the species L. abdullahbayrami examined by us, 7 different proteins were found as a result of transcriptome analysis; Breast cancer anti-oestrogen resistance protein 3-like (amino acid sequence length 910), BRCA2 interacting transcriptional repressor EMSY-like isoform X2 (amino acid sequence length 888), apoptosis regulator R1-like (amino acid sequence length 189), venom phosphodiesterase 2 (amino acid sequence length 770), serologically defined homolog of colorectal cancer antigen 3 (amino acid sequence length 377), C3 and PZP-like alpha-2-macroglobulin domain-containing protein 8 (amino acid sequence length 367) and colorectal cancer mutant protein-like isoform X2 (amino acid sequence length 970).
Uzair et al. [34] conducted research on the biological activities of scorpion venom in antimicrobial, antiviral, anti-cancer, and immune diseases. This review also de-scribes the evolutionary perspective of peptides derived from different scorpion venoms. The most important poison peptides are Ctriporin, Chlorotoxins (cltx), Neopladine I and II, Meucin 24, Meucin 25, and Hp 1090. The most well-known scorpion species with pharmaceutical activity; Pandinus imperator, Chaerilustricostatus, Buthus martensii, Mesobuthus eupeus, Leiurus quinnquestriatus, Tityus disrepans, and Heterometrus bengalensis. The role of peptides in cardiovascular events and osteoporosis treatment demonstrates their importance. The role of peptides against pathogens, skin infections, pain-relieving effects, and anti-malarial and anti-viral effects are discussed in detail [34]. Suhas [35] compiled the latest developments regarding the therapeutic applications of scorpion peptides. In most cases, the mechanism of action, as well as the primary sequence of the peptides, are given, and it therefore seems appropriate to investigate lead molecules for further development. Therefore, the relevant findings presented here can serve as a valuable resource for both improving the pharmacological profile and developing new drugs [35].
The end products of cellular regulatory mechanisms are called metabolites. The content of metabolites is the final response of biological systems to genetic and environmen-tal changes [36]. The goal of metabolomics is to analyze all small molecules in a biological system. Although metabolomics is not yet as mature as genomics and proteomics, it is a more promising technology than others for finding biomarkers for diseases such as cancer [36]. There are few publications investigating the low molecular weight fractions of venoms (frogs, spiders, snakes, scorpions, and wasps) [5]. Hu et al. detected metabolites in the secretions of live scorpions and frogs using ionization mass spectrometry. Lysine, serotonin, tryptophan, and some lipids were identified in the MS spectra [37]. Amino acids found in the secretions of spiders, scorpions, and frogs serve as precursors of monoamines. Both classes of metabolites have variable biological functions in venoms or intoxica-tions. Lysine and tryptophan in the venom of the scorpion Tityus serrulatus immobilize the prey and prevent it from escaping [38].
Conclusion
In this study, the amounts of free amino acids in the venoms of A.crassicauda, H. saulcyi and L. abdullahbayrami were determined by LC-MS/MS methods. According to the LC-MS/MS results, the presence of the amino acids taurine, alpha-aminobutyric acid, phosphoethanolamine, lysine, leucine and arginine was detected in the scorpion venom of A. crassicauda. H. saulcyi in scorpion venom; the amino acids taurine, lysine, phosphoethanolamine, arginine, alpha-aminopimelic acid and leucine were detected. The presence of the amino acids alpha-aminobutyric acid, taurine, lysine, phenylalanine, arginosuccinic acid, leucine, histamine, arginine and proline was detected in the venom of the scorpion L.abdullahbayrami. Our study was the first worldwide to perform transcriptomic analyses of mRNA transcripts in the venom glands of the scorpion species of A. carsicauda, H.saulcyi, and L.abdullahbayrami and metabolic analyses of their venom in their tissues. In the transcriptome study of these scorpion species, amino acid sequences in possible proteins in the venom glands were determined, and the venom contents and amino acids in the venom were compared by examining the profile of free amino acids. In addition, by revealing the amino acid profile of the scorpion venom using molecular biology methods, data were obtained that will contribute to the development of new treatment methods in cancer treatment, and proteins that may have the potential for cancer treatment were identified with the data obtained from this study.

